jev-benchmarks
Probability-aware evaluation for typed decision models: calibration, selective risk, latency, reproducible.
Benchmarks and evalsOutput verification
Home / Benchmarks, evals and calibration
27 entries
Probability-aware evaluation for typed decision models: calibration, selective risk, latency, reproducible.
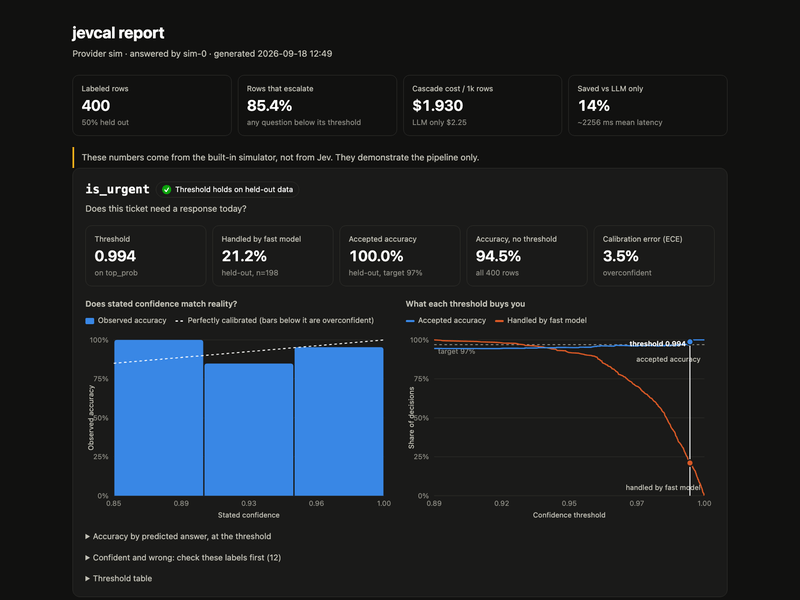
Stop guessing thresholds: calibrate, threshold, and drift-check against an LLM teacher.
Jev against Cohere Rerank, ZeroEntropy, and a chat baseline on 14 datasets, raw responses included.
Does a Jev rerank beat embedding search? 9,831 graded pairs, with the judge-circularity bias measured.
Blind benchmarks for prompt injection and vulnerable-code detection.
Jev against Claude Haiku on 2,000 phishing emails: accuracy, calibration, latency, cost.
Zero-shot spam filtering with Noul questions against TF-IDF baselines.
Jev against a strong LLM on the Who and When agent-failure-attribution benchmark.
Korean understanding and medical text, with runtime and cost evidence.
Independent Chinese research report: 52 pages, 50 reproducible tests, 143 traceable data rows.
Two benchmarks, chess and predator identification, one inside Jev's lane and one outside, both with results.
Reproducible calibration and selective-risk benchmarks for Jev decisions in DSPy.
Personal-assistant agent with 100 mocked tools, measuring how many steps a Jev-gated agent needs.
Choice and Noul questions scored against ASReview SYNERGY gold labels for abstract screening.
Measures whether ORDER BY over a Jev probability is defensible: pairwise inversion, Score ordinality against a human grade, calibration, and wording invariants under a pre-registered gate; passes on 20 Newsgroups topics, fails four of six conditions on Amazon ESCI product relevance, and shows that a 40-row batched state through a DuckDB extension fails the ranking gate one row per request passes.
Pinecone's skill-testing CLI, with a Jev grading backend it reports at about 30 times cheaper than the LLM grader.
Jev against GPT-5.6 Terra on three labeled tasks: equal on the easy ones, 6.7 points lower on 77-way routing, 5 times faster, 41 to 50 times cheaper.
Tool-call risk classification with the run-to-run variance reported; every wrong answer came with hedged confidence.
Reproducible harness over a pinned jev-ultrafast commit, with baseline and stress suites.
Jev against other models in games with explicit states, legal actions, and a measurable outcome.
Hosted arena that puts Jev against an opponent judge you connect and takes your vote before revealing which was which, with latency, cost provenance, and self-reported confidence; a vote records preference, not verified correctness.
Benchmark for Jev-class decision models: bounded rubric in, typed answer with a probability per option out, with cascade and committee experiments reported separately.
Finds the examples a Jev function is least sure about, asks you to label them, and improves the function with GEPA.
Measures what a Jev request is billed and how its answers hold up under batching, translation, and rewording, from 3,455 billed requests with public raw logs.
Confidence gates, shadow mode, recipes, and evals; reports Claude CLI at 48.9 s against Jev at 1.3 s on the same row-filter job.
Runs a trace's agent, quality, and security evals as one batch of typed Jev questions instead of separate LLM-judge calls.
Controlled prompt experiments on jev-1.13.0, raw results and offline verification.