human-compiler
Paste text, get diagnostics, like a compiler for prose.
Playgrounds and demosModeration and safety
Home / Safety, moderation and verification
14 entries
Paste text, get diagnostics, like a compiler for prose.
Low-latency audio censorship proof of concept: Jev typed decisions drive ffmpeg.
Checks claims against cited excerpts with Jev in an English and Romanian fact-checking site, with a public integration example and a closed-source full application.
Chat moderation with editable rules.
Sends an agent skill's text to Jev before installation and returns a verdict with category scores, without loading the skill into the agent's context; the submitted text is not redacted for secrets.
Telegram bot that removes spam and scam messages from group chats on calibrated-confidence classification.
Does the cited paper support the sentence citing it? Claude finds the quote, Jev scores it, a human decides.
Prose linter for AI writing tells: countable rules plus one judgment model.
AI SDK middleware and proxy that runs seven Jev checks on every LLM response before the user sees it; no accuracy numbers yet, and it says so.
Semantic MCP firewall that screens every tool call, result, and description; reports 94 percent block recall at about $0.00002 a check.
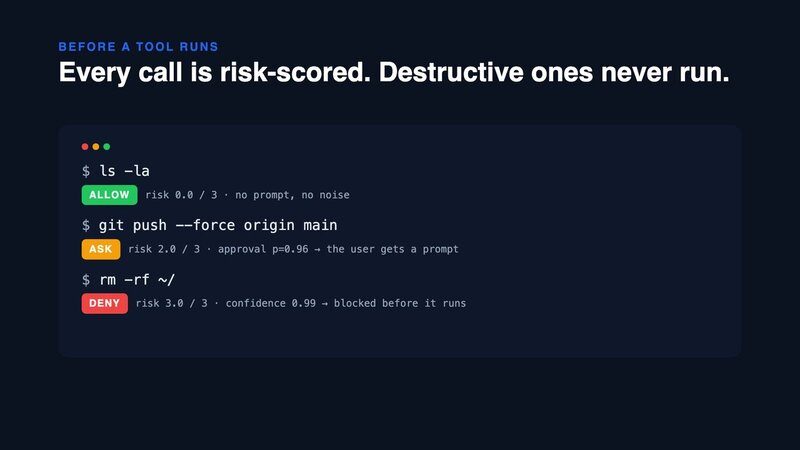
Auto mode for Claude Code, Codex, Cursor, Gemini CLI, Pi, and OpenCode: risk-scores each tool call as deny, ask, or allow and flags prompt injection in results.
Measures how well Jev spots real credentials in file snippets, with the hard config-shaped cases scored separately.
Scans a codebase for hidden or data-stealing behavior before you run it; a clean report is not proof, and it says so.